What the Microsoft outage reveals about the cloud
Sussex’s email disruption shows how an organisation’s choice of provider can affect students, while leaving other services working.
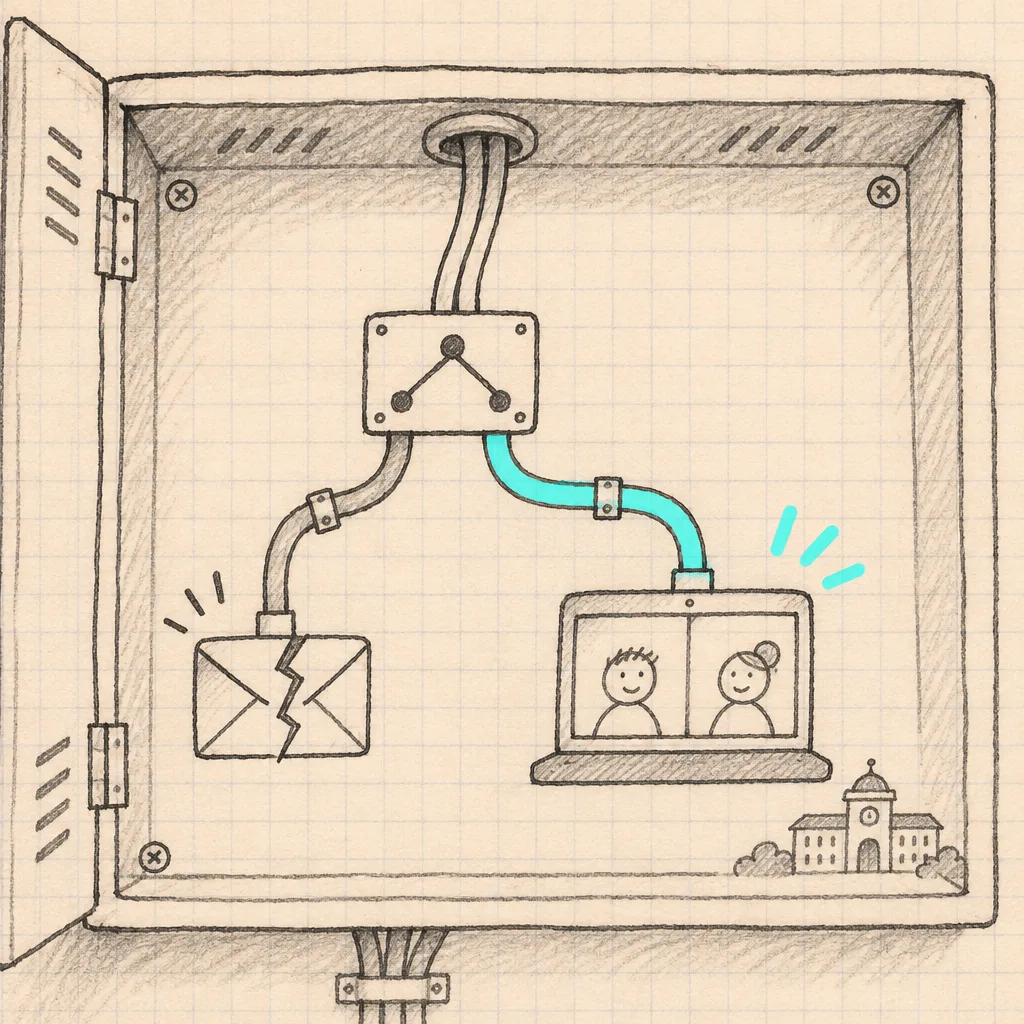
Microsoft’s online services disruption left organisations dealing with inaccessible email on 13 November 2026. At the University of Sussex, an update at 10am that day said email was unavailable, while core Teams calls, meetings and chats were working.
That distinction matters. An outage is a period when a service does not work properly; it does not necessarily mean every app has stopped. Sussex said files in SharePoint and OneDrive were still accessible, although sharing links and calendar functions could be disrupted. A student might be able to join a meeting but not check the email containing its details.
To understand why, we need to start with the cloud. The word sounds like a place without an owner. In plain terms, it usually means using computing services run on machines elsewhere, over a network. A server is one of those machines: it provides a service, such as storing a file or delivering a message, to other devices.
When your college uses a cloud email service, the app on your phone is only one part of the system. It connects through the internet to computers operated for the provider. Those computers handle work such as finding your mailbox and passing messages on. The college still manages things such as your account and who may access it, but the provider runs much of the equipment behind the service. Microsoft’s own guidance describes this division of responsibility for its cloud products.
Here is how a disruption can spread. A student sends an email. Their phone connects to the provider’s service. If the machines handling that connection are unavailable or overloaded, the message may not get through as expected. Microsoft said some servers had unexpectedly become unavailable, putting pressure on the machines still operating. It reported recovery work, but that was not the same as a completed explanation of why the incident began.
Different functions can use different parts of the system. That helps explain why Sussex could report working Teams calls alongside inaccessible email. It does not establish that Teams worked for everyone, everywhere. Nor does an email problem establish that every Microsoft service was down.
The choice to use a particular cloud service is made by people in an organisation. Leaders and technical staff can choose a supplier, decide which jobs to place with it and arrange an alternative. The precise people who approved the arrangements at Sussex or West Northamptonshire Council are not identified in their outage notices. We should not mistake an unknown decision-maker for a decision nobody made.
There are reasons organisations make this choice. A provider can supply managed equipment, updates and specialist staff that a school or council might struggle to provide itself. Microsoft earns revenue from customer subscriptions. Customers receive services in return, but when several essential jobs rely on the same provider, a problem there can interrupt more than one part of their work.
The costs of interruption fall elsewhere too. Coregas, an Australian gas supplier, asked customers to order by phone. That meant customers had to change how they ordered and staff had to handle those calls; its notice did not put a price on the disruption. West Northamptonshire Council said its email was affected but its website and telephone contact remained available. Neither example means every affected organisation was reachable only by phone.
There is another way to organise some of this work. Open-source software is software whose underlying instructions can be studied, changed and shared under its licence. Self-hosting means an organisation runs a service under its own control, on its own equipment or on rented computers it administers. These are different choices: open-source software can be hosted by a supplier, and self-hosted software need not be open source.
An organisation could, for example, run an open-source file-sharing service on independently operated equipment. If it controls the software and where it runs, it has more choice over its settings, maintenance and a move to another host. That is why open-source, self-hosted solutions can win: they can give an organisation control rather than leaving every important decision with one cloud supplier.
But control brings work. Someone must install security updates, protect accounts, watch for failures and maintain backups, which are separate copies kept for recovery. If the organisation’s server fails, or the building loses its internet connection, staff may still be unable to reach the service. A backup stored only beside that server could be lost in the same incident. An independent copy and a tested way to restore it matter more than the label on the software.
Self-hosting is not a guarantee that Sussex’s email would have stayed available. The answer depends on who maintained the alternative, where it ran, how it connected to users and whether its recovery arrangements worked. It could also depend on Microsoft for sign-in or another essential component. A well-maintained independent service can reduce one kind of dependence; an understaffed one can create a different risk.
Now consider a headline calling this a worldwide outage. Worldwide can mean people in several parts of the world reported problems. It does not tell you that every customer, country or app was affected. Deutsche Welle reported nearly 130,000 US Outlook problem reports on Downdetector; those were voluntary reports, not a verified count of affected people worldwide.
To check the claim, look for the provider’s dated service update, then compare it with notices from organisations in different places. Ask which function each notice describes, when it was checked and whether it reports a problem or a recovery. A working call in Sussex and a failed email there can both be true. Neither observation tells us the experience of every user.
Keep going
 How it works
How Cumberland’s new council wards were decided
The new electoral map changes who represents neighbourhoods without moving the council’s outer boundary, and Parliament had a chance to stop it.
 How it works
What Wales’s automatic voter registration means
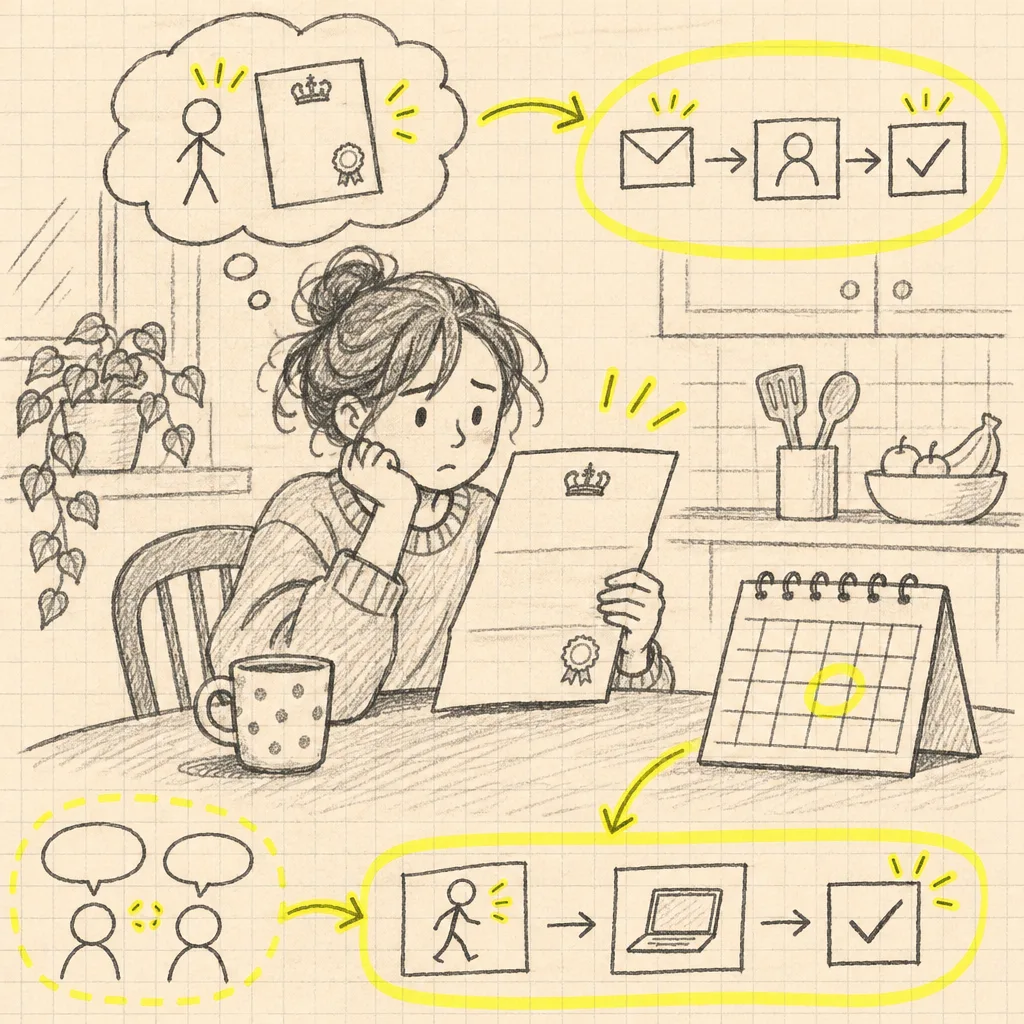
A notice about council elections does not mean you are registered for UK Parliament elections, and you have choices before your name is added.
 How it works
What a phoenix company is, and what it is not
The Insolvency Service wants earlier action on abusive phoenixism, but a business restart is not automatically fraud.